Reference and study · updated

AI crawlers: every robots.txt name, and the major websites that block them

34 AI crawlers and opt-out tokens, each described from its operator's own page: what it collects, and what the operator says about robots.txt.

We read the robots.txt files of 137 major websites the way RFC 9309 tells a crawler to. 50 of them (36%) block at least one AI training crawler from every page. GPTBot is blocked by 38 (28%) and ClaudeBot by 37 (27%); 25 block GPTBot but let OpenAI's search crawler in. 81 block none of them (59%).

34AI crawlers and tokens listed 137major websites' robots.txt read 38block GPTBot from every page 50block at least one AI training crawler

Check any website's robots.txtBuild robots.txt rulesDownload the CSVCite

Which AI crawlers major websites block

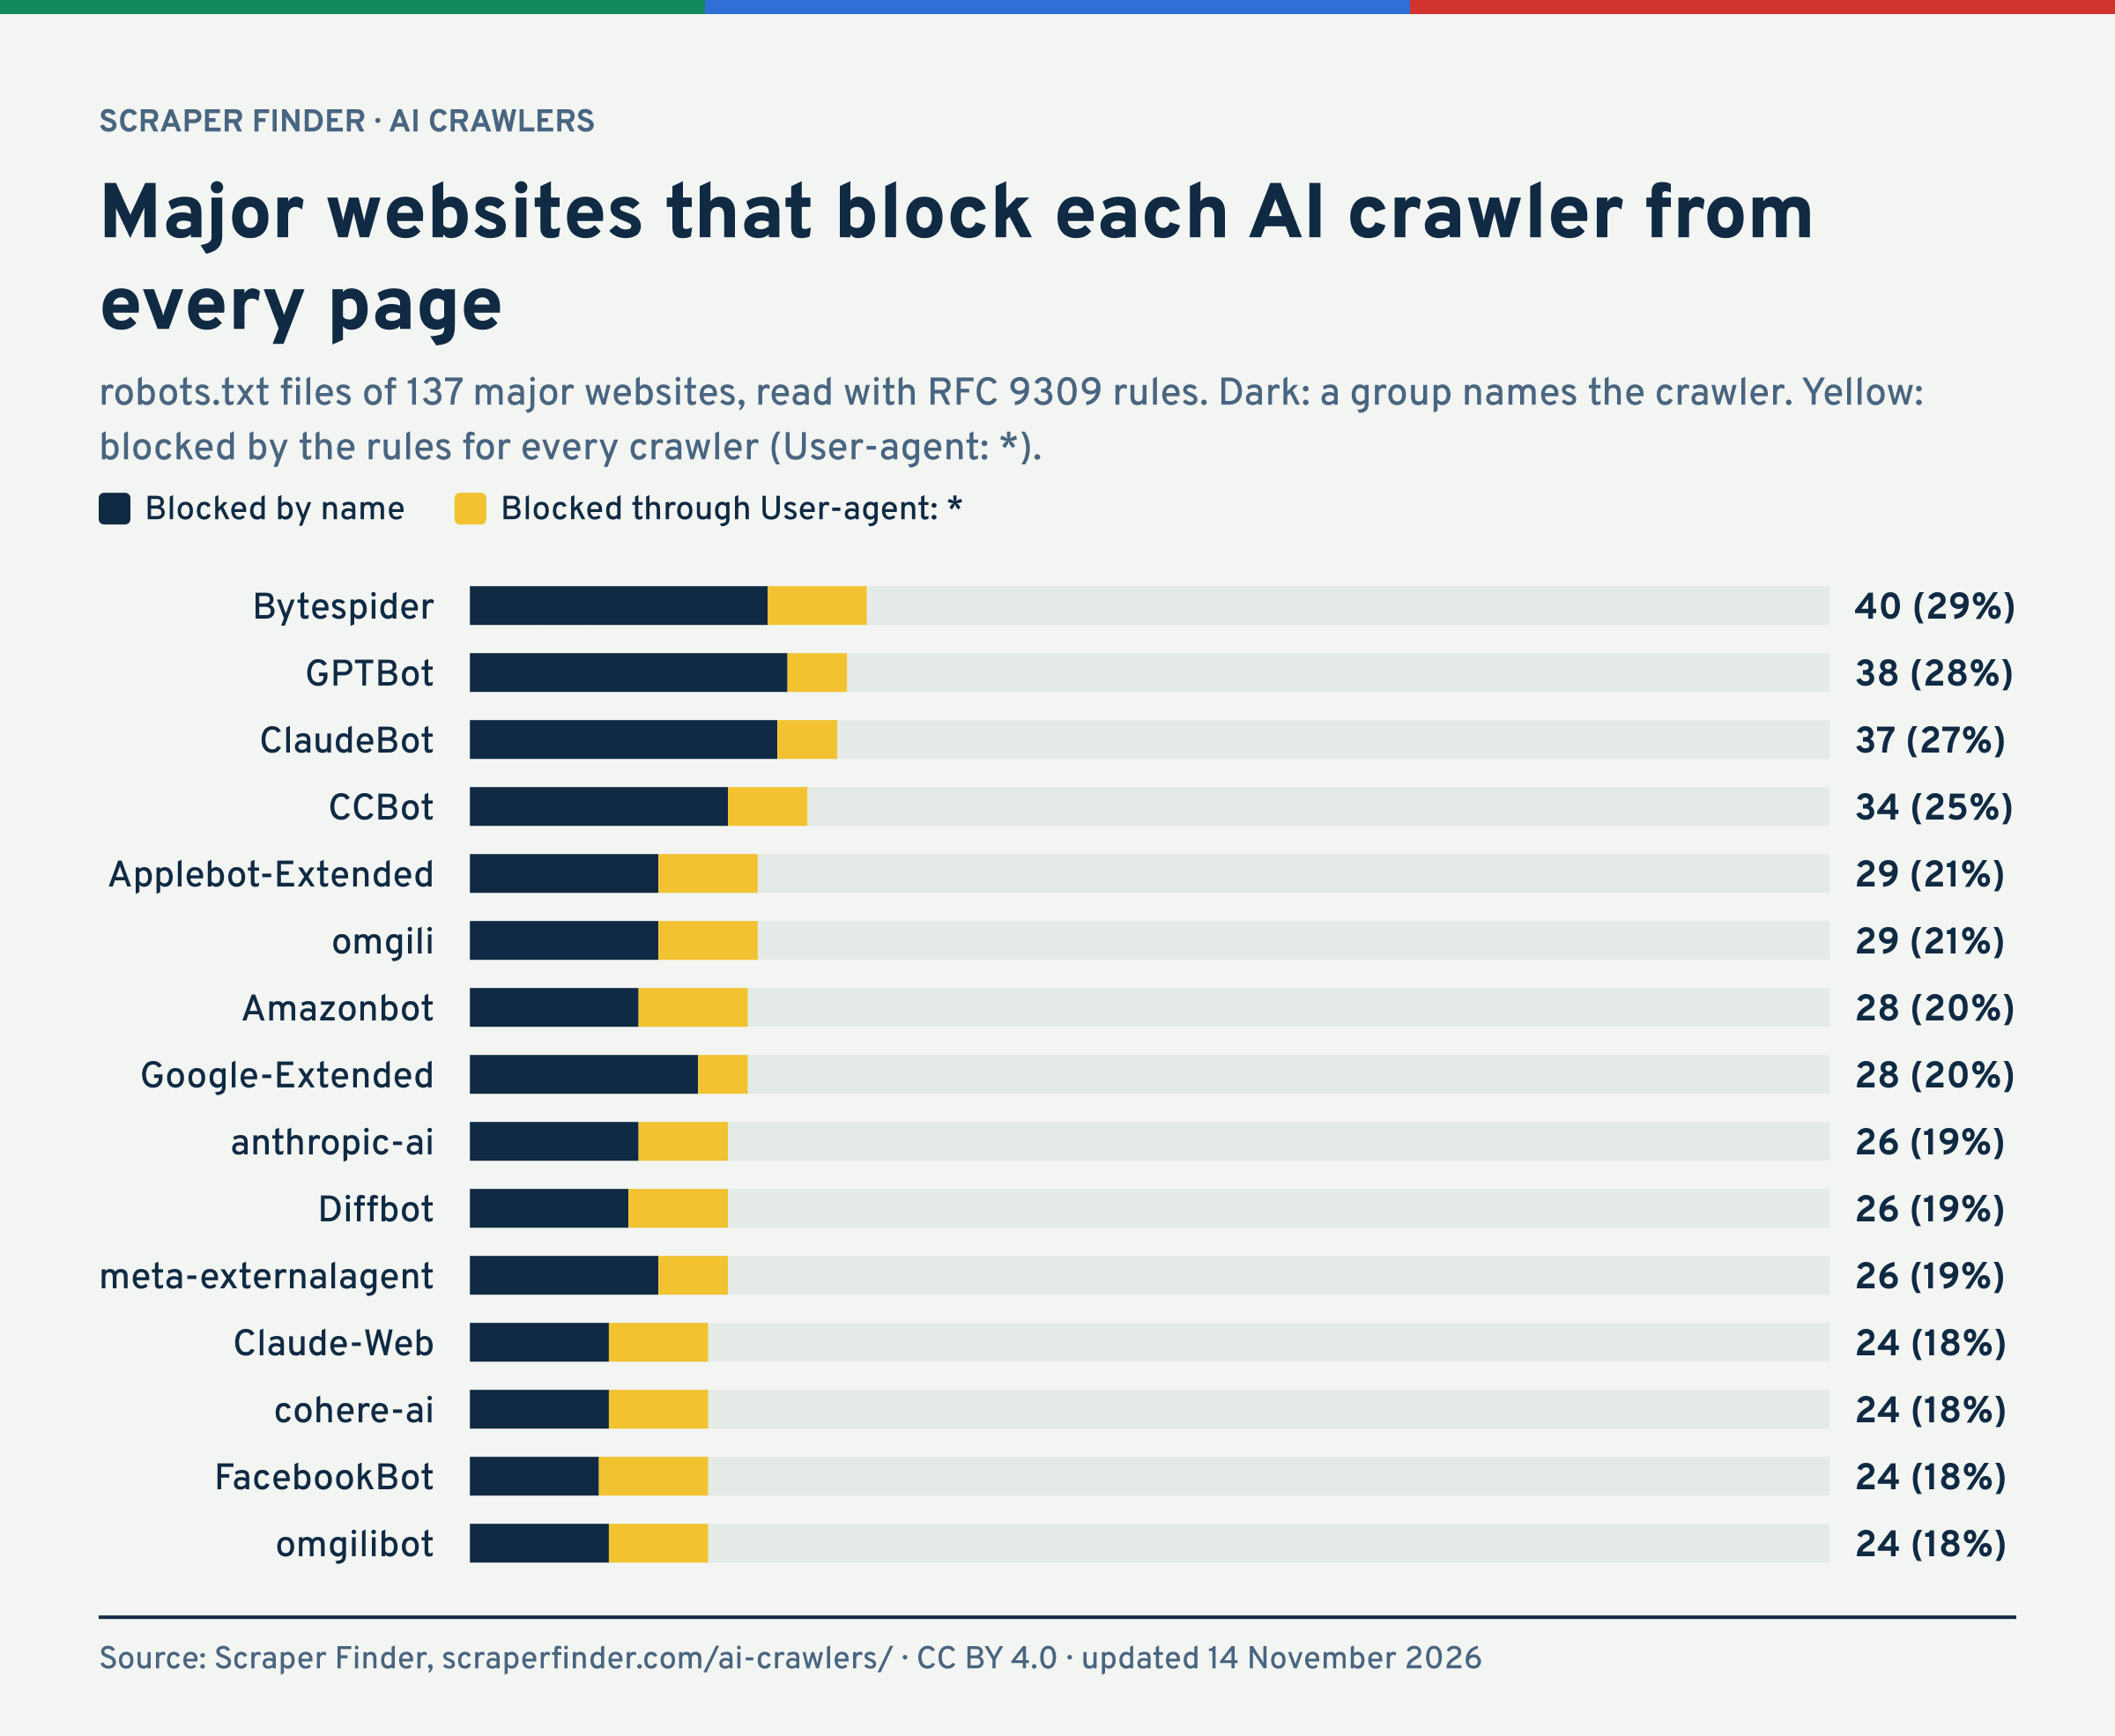
Each bar counts the websites whose robots.txt keeps the crawler off every page: by naming it in a group of its own (dark), or only through the rules for every crawler, User-agent: * (yellow). Out of 137 websites whose file could be read.

  1. Bytespider 40
  2. GPTBot 38
  3. ClaudeBot 37
  4. CCBot 34
  5. Applebot-Extended 29
  6. omgili 29
  7. Amazonbot 28
  8. Google-Extended 28
  9. anthropic-ai 26
  10. Diffbot 26
  11. meta-externalagent 26
  12. Claude-Web 24
  13. cohere-ai 24
  14. FacebookBot 24
  15. omgilibot 24
  16. AI2Bot 23
  17. ChatGPT-User 21
  18. img2dataset 21
  19. PerplexityBot 21
  20. YouBot 21
  21. Google-CloudVertexBot 20
  22. Perplexity-User 18
  23. Claude-User 17
  24. MistralAI-Training 17
  25. meta-externalfetcher 16
  26. MistralAI-User 16
  27. DuckAssistBot 15
  28. meta-webindexer 15
  29. OAI-AdsBot 15
  30. Amzn-SearchBot 14
  31. Claude-SearchBot 14
  32. MistralAI-Index 14
  33. Amzn-User 13
  34. OAI-SearchBot 13

"Every page" means the home page and any other page are disallowed. Websites that close only some paths to a crawler are counted in the CSV, with the crawler-by-crawler verdict for each website.

The directory

The name to write after User-agent:, who runs it, what it is for and what its operator says about robots.txt, read on 14 November 2026. Follow the source link before you rely on a line: operators change these pages.

Collects pages for AI training

Collect pages that may train AI models. These are the ones most robots.txt rules are written for.

GPTBot

OpenAI

Crawls pages that may be used to train OpenAI's generative AI foundation models.

robots.txt: OpenAI: disallowing GPTBot says the site's content should not be used to train its foundation models.

38 of 137 major websites block it from every page; 47 name it.

Operator's page

ClaudeBot

Anthropic

Collects web content that may be used to train and develop Anthropic's models.

robots.txt: Anthropic: its bots honour robots.txt directives.

37 of 137 major websites block it from every page; 44 name it.

Operator's page

meta-externalagent

Meta

Crawls the web for training AI models and for improving products by indexing content.

robots.txt: Meta documents blocking it with robots.txt disallow rules.

26 of 137 major websites block it from every page; 29 name it.

Operator's page

Amazonbot

Amazon

Improves Amazon's products and services. Amazon says what it collects may be used to train Amazon AI models.

robots.txt: Amazon: honours the user-agent and allow/disallow rules in robots.txt.

28 of 137 major websites block it from every page; 25 name it.

Operator's page

MistralAI-Training

Mistral AI

Collects web content for datasets that train Mistral's generative AI models.

robots.txt: Mistral: webmasters can disallow it in robots.txt.

17 of 137 major websites block it from every page; 3 name it.

Operator's page

AI2Bot

Allen Institute for AI

Discovers web content used to train the Allen Institute's open language models.

robots.txt: The operator's page does not say how it treats robots.txt.

23 of 137 major websites block it from every page; 10 name it.

Operator's page

Opt-out token, not a crawler

No crawler sends these names. They are switches in robots.txt that decide whether pages a company's normal crawler collects may train its AI models.

Google-Extended

Google

A robots.txt token, not a crawler: it decides whether pages Google crawls may be used to train future Gemini models. It has no effect on Google Search.

robots.txt: Google: crawling is done with Google's usual user agents; Google-Extended only reads as a robots.txt group.

28 of 137 major websites block it from every page; 35 name it.

Operator's page

Applebot-Extended

Apple

A robots.txt token, not a crawler: it decides whether pages Applebot collects may train Apple's foundation models. Blocking it keeps pages in Apple's search features.

robots.txt: Apple: Applebot-Extended does not crawl; disallow it to opt out of model training.

29 of 137 major websites block it from every page; 26 name it.

Operator's page

Index pages so an AI search engine or assistant can find, cite and link them. Blocking them can take a site out of those answers.

OAI-SearchBot

OpenAI

Finds and surfaces websites in ChatGPT search results.

robots.txt: OpenAI: sites that opt out of OAI-SearchBot are not shown in ChatGPT search answers.

13 of 137 major websites block it from every page; 32 name it.

Operator's page

Claude-SearchBot

Anthropic

Indexes pages to improve the quality of Claude's search results.

robots.txt: Anthropic: its bots honour robots.txt directives.

14 of 137 major websites block it from every page; 24 name it.

Operator's page

PerplexityBot

Perplexity

Surfaces and links websites in Perplexity search results. Perplexity says it is not used to crawl for AI model training.

robots.txt: Perplexity: allow it in robots.txt for your site to appear in its search results.

21 of 137 major websites block it from every page; 35 name it.

Operator's page

meta-webindexer

Meta

Crawls the web to improve the quality of Meta AI search results.

robots.txt: Meta: allowing it in robots.txt helps Meta cite and link your content.

15 of 137 major websites block it from every page; 8 name it.

Operator's page

Amzn-SearchBot

Amazon

Improves search experiences in Amazon products. Amazon says it does not crawl for generative AI training.

robots.txt: Amazon: honours the user-agent and allow/disallow rules in robots.txt.

14 of 137 major websites block it from every page; 3 name it.

Operator's page

MistralAI-Index

Mistral AI

Indexes pages for Mistral's search. Mistral says the content is not used for AI training of any kind.

robots.txt: Mistral's page says nothing more about robots.txt for this agent.

14 of 137 major websites block it from every page; 1 name it.

Operator's page

DuckAssistBot

DuckDuckGo

Fetches pages in real time for DuckDuckGo's AI-assisted answers, which cite their sources. DuckDuckGo says the data never trains AI models.

robots.txt: DuckDuckGo: respects robots.txt; a change takes effect within 72 hours.

15 of 137 major websites block it from every page; 11 name it.

Operator's page

YouBot

You.com

Discovers and indexes pages for You.com search results.

robots.txt: You.com: fully respects robots.txt and caches it for 30 minutes.

21 of 137 major websites block it from every page; 10 name it.

Operator's page

Fetches a page when a person asks

Fetch one page because a person asked an assistant about it. Several operators say robots.txt may not apply to them.

ChatGPT-User

OpenAI

Visits a page when a person's request in ChatGPT or a custom GPT needs it.

robots.txt: OpenAI: because a user starts these visits, robots.txt rules may not apply.

21 of 137 major websites block it from every page; 37 name it.

Operator's page

Claude-User

Anthropic

Fetches a page when a Claude user asks something that needs it.

robots.txt: Anthropic: its bots honour robots.txt directives, this one included.

17 of 137 major websites block it from every page; 24 name it.

Operator's page

Perplexity-User

Perplexity

Visits a page when a Perplexity user's question needs it.

robots.txt: Perplexity: because a user asked for the page, this fetcher generally ignores robots.txt rules.

18 of 137 major websites block it from every page; 16 name it.

Operator's page

meta-externalfetcher

Meta

Fetches individual links a user asks for, for Meta's agentic AI features.

robots.txt: Meta: because the fetches are user requested, it may bypass robots.txt rules.

16 of 137 major websites block it from every page; 12 name it.

Operator's page

Amzn-User

Amazon

Supports user actions, such as Alexa answers that need current information. Amazon says it does not crawl for generative AI training.

robots.txt: Amazon: honours the user-agent and allow/disallow rules in robots.txt.

13 of 137 major websites block it from every page; 2 name it.

Operator's page

MistralAI-User

Mistral AI

Visits a page when a user of Mistral's assistant asks for it. Not an automatic crawler.

robots.txt: Mistral: robots.txt decides which sites these user requests may reach.

16 of 137 major websites block it from every page; 4 name it.

Operator's page

Builds a web dataset others use

Build web collections that other companies and researchers download.

CCBot

Common Crawl

Builds Common Crawl, an open repository of web crawl data that anyone can download and analyse.

robots.txt: Common Crawl: CCBot respects robots.txt.

34 of 137 major websites block it from every page; 36 name it.

Operator's page

omgili

Webz.io

The crawler behind Webz.io, a web data service used by media monitors and research institutes.

robots.txt: Webz.io: says it always complies with robots.txt requests.

29 of 137 major websites block it from every page; 20 name it.

Operator's page

Other AI use

AI-related agents with a narrower job.

OAI-AdsBot

OpenAI

Checks the safety of web pages submitted as ads on ChatGPT.

robots.txt: OpenAI's page gives no robots.txt guidance for it.

15 of 137 major websites block it from every page; 4 name it.

Operator's page

Google-CloudVertexBot

Google

Crawls sites whose owners asked for it, to build Vertex AI Agents. No effect on Google Search.

robots.txt: Listed among Google's common crawlers, which follow robots.txt.

20 of 137 major websites block it from every page; 10 name it.

Operator's page

img2dataset

Open-source tool

The name of img2dataset, an open-source program that downloads large image collections for AI datasets. Anyone can run it; it is not one company's crawler.

robots.txt: No operator page.

21 of 137 major websites block it from every page; 8 name it.

No operator page

Older name, no longer documented

Older names that still fill many robots.txt files. Their operators no longer list them.

anthropic-ai

Anthropic

An older name many robots.txt files still carry. It is not on Anthropic's current crawler page.

robots.txt: Not on the operator's current page.

26 of 137 major websites block it from every page; 23 name it.

Operator's page

Claude-Web

Anthropic

An older name many robots.txt files still carry. It is not on Anthropic's current crawler page.

robots.txt: Not on the operator's current page.

24 of 137 major websites block it from every page; 17 name it.

Operator's page

FacebookBot

Meta

An older Meta name many robots.txt files still carry. It is not on Meta's current crawler page.

robots.txt: Not on the operator's current page.

24 of 137 major websites block it from every page; 16 name it.

Operator's page

omgilibot

Webz.io

An older name of Webz.io's crawler. Webz.io's own post gives the agent as omgili.

robots.txt: Not on the operator's current page.

24 of 137 major websites block it from every page; 15 name it.

Operator's page

No operator documentation

Names found in robots.txt files whose operator publishes no page about them.

Bytespider

ByteDance

A crawler third parties attribute to ByteDance. ByteDance publishes no page about it.

robots.txt: No operator statement found.

40 of 137 major websites block it from every page; 33 name it.

No operator page

cohere-ai

Cohere

A name many block lists carry. Cohere's crawler page does not list it and says Cohere does not crawl to train generative AI models at this time.

robots.txt: Cohere's page names no active agent and says its crawlers must respect robots.txt.

24 of 137 major websites block it from every page; 16 name it.

Operator's page

Diffbot

Diffbot

The crawler of Diffbot, which sells web extraction and a knowledge graph. Diffbot's documentation has no crawler page.

robots.txt: No operator statement found.

26 of 137 major websites block it from every page; 18 name it.

Operator's page

Build your robots.txt rules

Tick what you want to keep out. The rules update as you go; paste them into your robots.txt above or below your other groups.

Start from
Crawlers

Collects pages for AI training

Opt-out token, not a crawler

Indexes pages for AI search and answers

Fetches a page when a person asks

Builds a web dataset others use

Other AI use

Older name, no longer documented

No operator documentation

# Tick a crawler or pick a starting point.

One group lists every ticked name and closes the whole site to them. A crawler with its own group stops reading your User-agent: * rules, so anything you still want it to follow belongs in this group too. User-triggered fetchers may ignore the file; see each entry above.

Method

  • The directory comes from each operator's own documentation, read on 14 November 2026, in our words, never more than the operator says. Where an operator says nothing about robots.txt, the entry says so. Names with no operator page are marked as such.
  • The websites are the 172 this atlas maps. Once a week the site asks each for its robots.txt with one plain HTTPS request (its www host if the bare domain has none); 137 answered with a file that could be read, on 14 November 2026.
  • The verdicts follow RFC 9309, the robots.txt standard: a crawler obeys every group that names it, else the User-agent: * groups; the longest matching rule wins and Allow wins a tie. "Every page" means the home page and an ordinary deep page are both disallowed. The same reader runs in the live checker and is tested against shared cases.

What this does not measure

What a crawler actually does. robots.txt states a wish; it cannot show firewalls, bot-management rules, paywalls or crawlers that ignore it. A website whose robots.txt could not be read is left out of the counts, never guessed.

Download the data

One row per website, one column per crawler: blocked, blocked-except, partial or allowed, with +named when the website's own group for that crawler decides. The JSON adds the directory and the totals.

CSVJSON

Cite this study

Address: scraperfinder.com/ai-crawlers/ Last updated Licence: CC BY 4.0, free to reuse with a credit and a link

Scraper Finder. (2026, November 14). AI crawlers: every robots.txt name, and the major websites that block them [Data set]. https://scraperfinder.com/ai-crawlers/

Other formats: MLA, Chicago, HTML link, Markdown, BibTeX
MLA
Scraper Finder. "AI crawlers: every robots.txt name, and the major websites that block them." Scraper Finder, 14 Nov. 2026, scraperfinder.com/ai-crawlers/.
Chicago
Scraper Finder. "AI crawlers: every robots.txt name, and the major websites that block them." Last modified November 14, 2026. https://scraperfinder.com/ai-crawlers/.
HTML link
<a href="https://scraperfinder.com/ai-crawlers/">AI crawlers: every robots.txt name, and the major websites that block them</a> (Scraper Finder, updated 14 November 2026)
Markdown
[AI crawlers: every robots.txt name, and the major websites that block them](https://scraperfinder.com/ai-crawlers/) (Scraper Finder, updated 14 November 2026)
BibTeX
@misc{scraperfinder_aicrawlers_2026,
  author = {{Scraper Finder}},
  title = {AI crawlers: every robots.txt name, and the major websites that block them},
  year = {2026},
  howpublished = {\url{https://scraperfinder.com/ai-crawlers/}},
  note = {Last updated 14 November 2026}
}

Charts to download or embed

Each chart carries its source line inside the image. Use it in an article or a slide with a link to this page.

  • Bar chart: how many major websites' robots.txt files block each AI crawler from every page, by name or through User-agent: *

    Major websites that block each AI crawler from every page

    PNGSVG

    Embed code

Questions people ask

Does blocking GPTBot keep my site out of ChatGPT?

Not by itself. OpenAI documents three agents: GPTBot collects training data, OAI-SearchBot finds pages for ChatGPT search, and ChatGPT-User visits a page when a person asks. Blocking GPTBot asks OpenAI not to train on your pages; your pages can still appear in ChatGPT search unless OAI-SearchBot is blocked too.

Is Google-Extended a crawler I can see in my logs?

No. Google says Google-Extended has no user agent string of its own: Google's usual crawlers fetch the pages, and the Google-Extended group in robots.txt only decides whether they may be used to train Gemini models. It has no effect on Google Search. Applebot-Extended works the same way for Apple.

Do AI crawlers have to obey robots.txt?

robots.txt is a request, not a lock. Most operators listed here say their automatic crawlers honour it; OpenAI, Perplexity and Meta say their user-triggered fetchers may not. Blocking for certain takes a firewall or bot-management rule, which robots.txt cannot show.

Why does a group naming a crawler matter?

Under RFC 9309 a crawler obeys only the group that names it. If robots.txt has a GPTBot group, GPTBot ignores everything under User-agent: *. A site that blocks everyone with User-agent: * but adds an empty GPTBot group has let GPTBot in.

How often is this updated?

The robots.txt files are read again every week. Operator descriptions are re-checked when an operator changes its page; each entry links to the page it comes from. The date at the top moves only when a number changes.