Every number below is computed from public sources, dated, and recomputed when the sources change. Reuse it in articles, reports and slides with a credit to Scraper Finder and a link to the page.
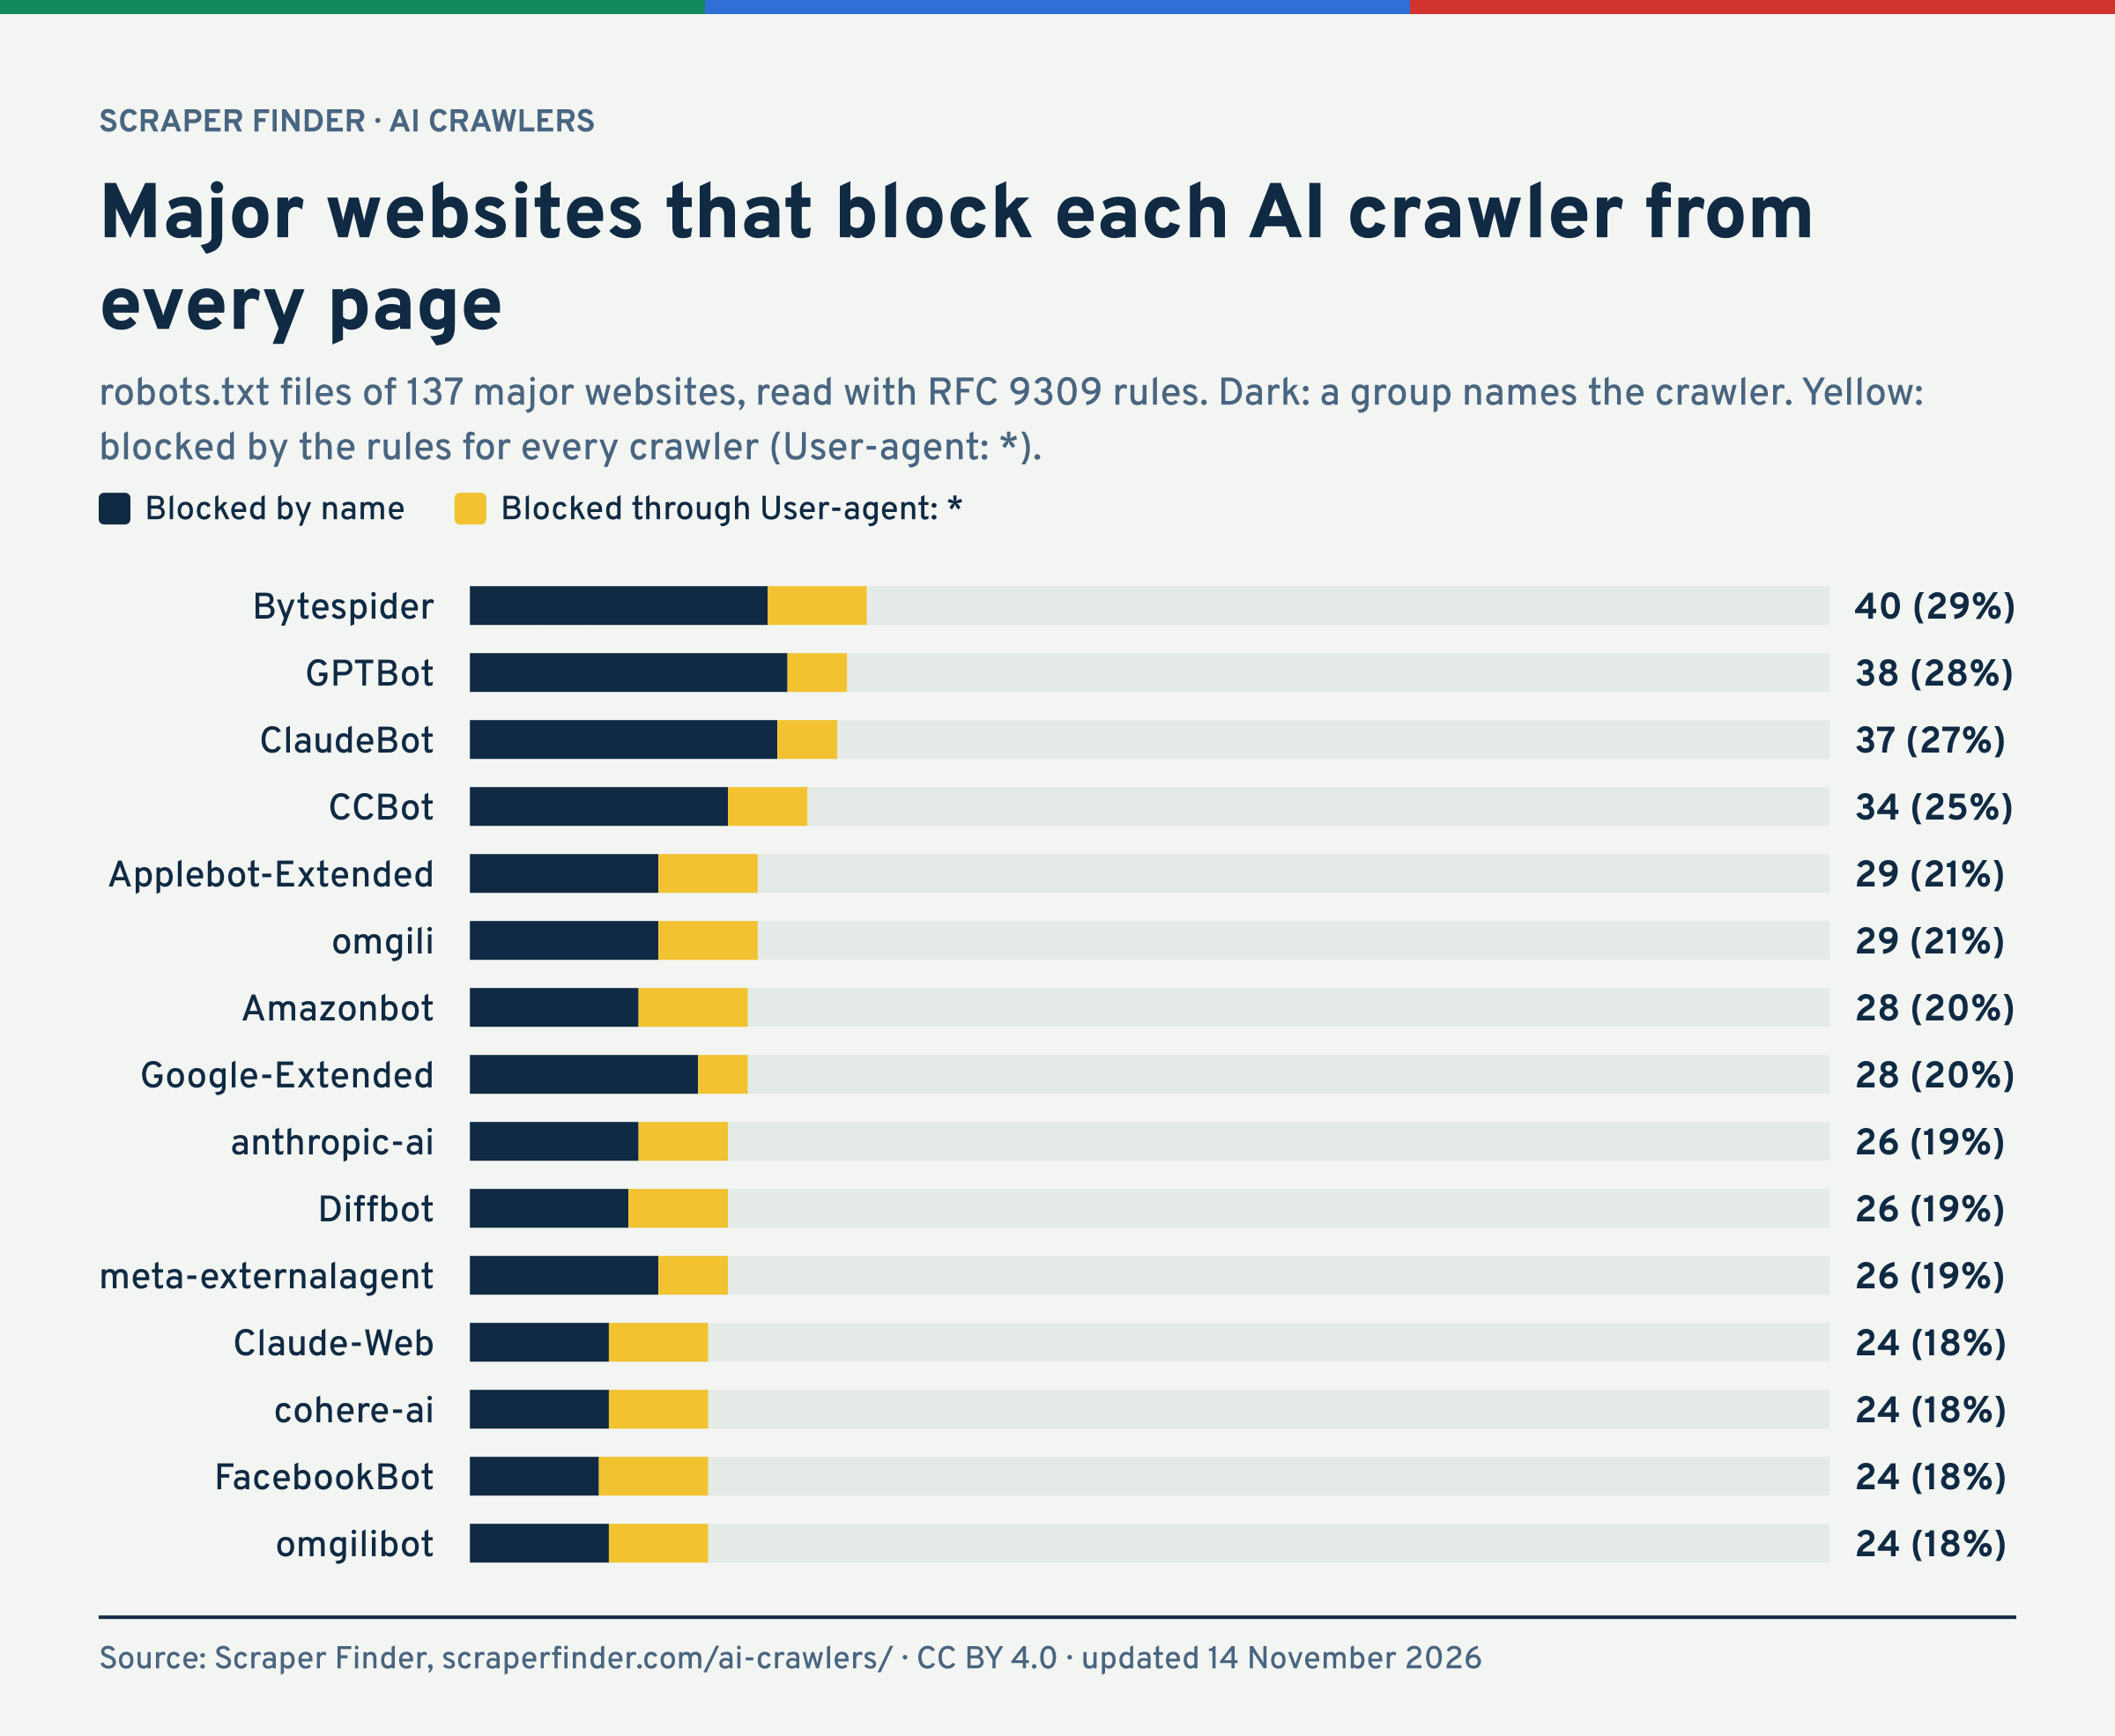
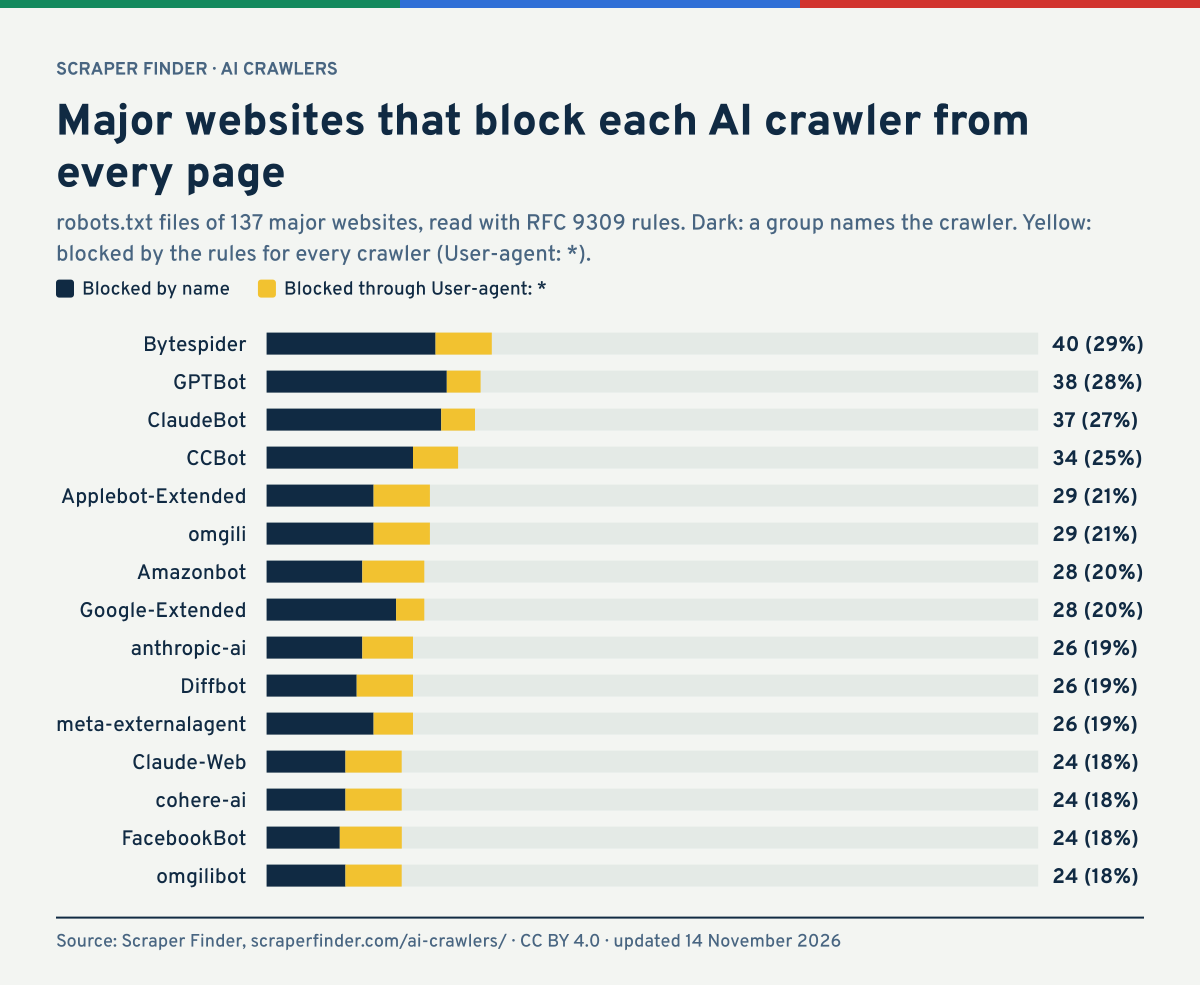
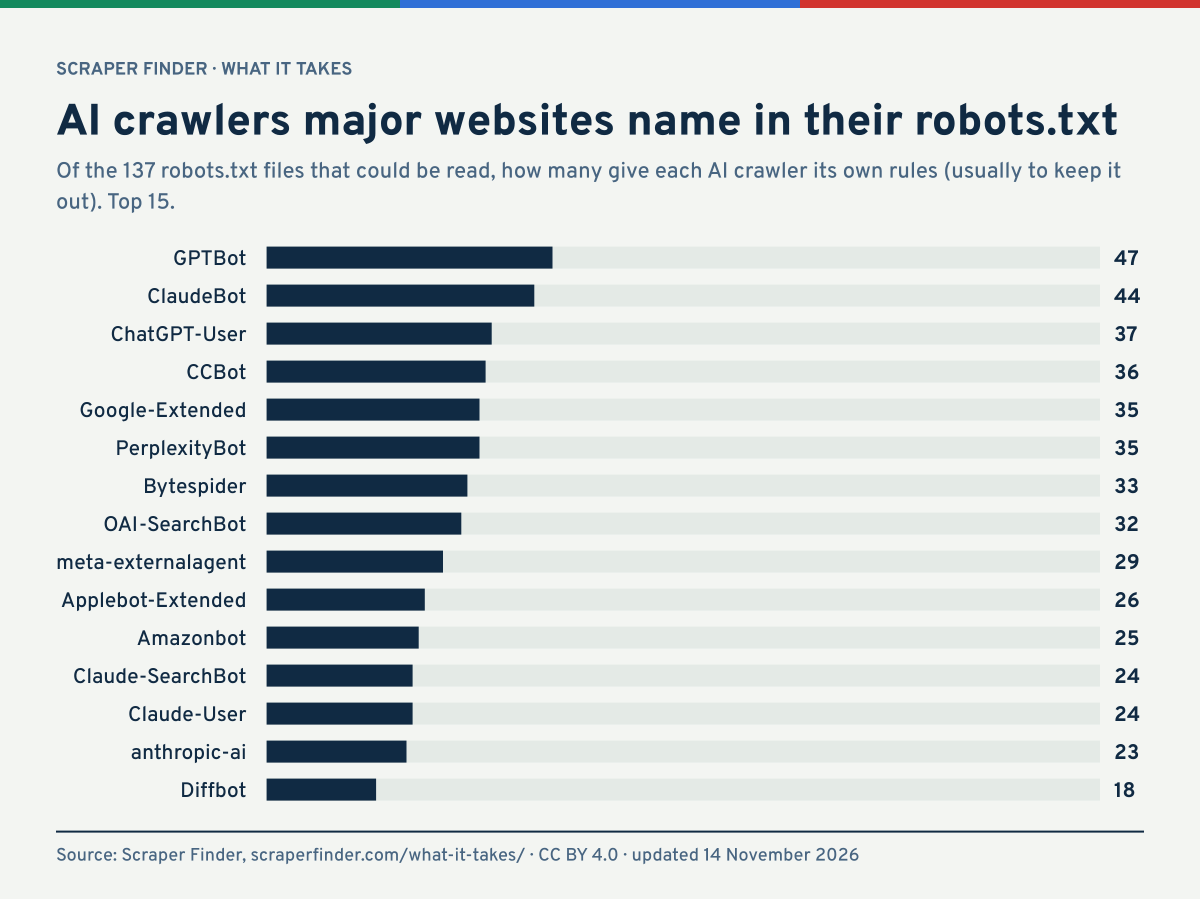
34 AI crawlers and opt-out tokens, each described from its operator's own page, and what the robots.txt files of 137 major websites tell each one under RFC 9309. 50 of them (36%) keep at least one AI training crawler off every page; GPTBot is blocked by 38 (28%), and 25 block GPTBot while letting OpenAI's search crawler in. Refreshed every week.
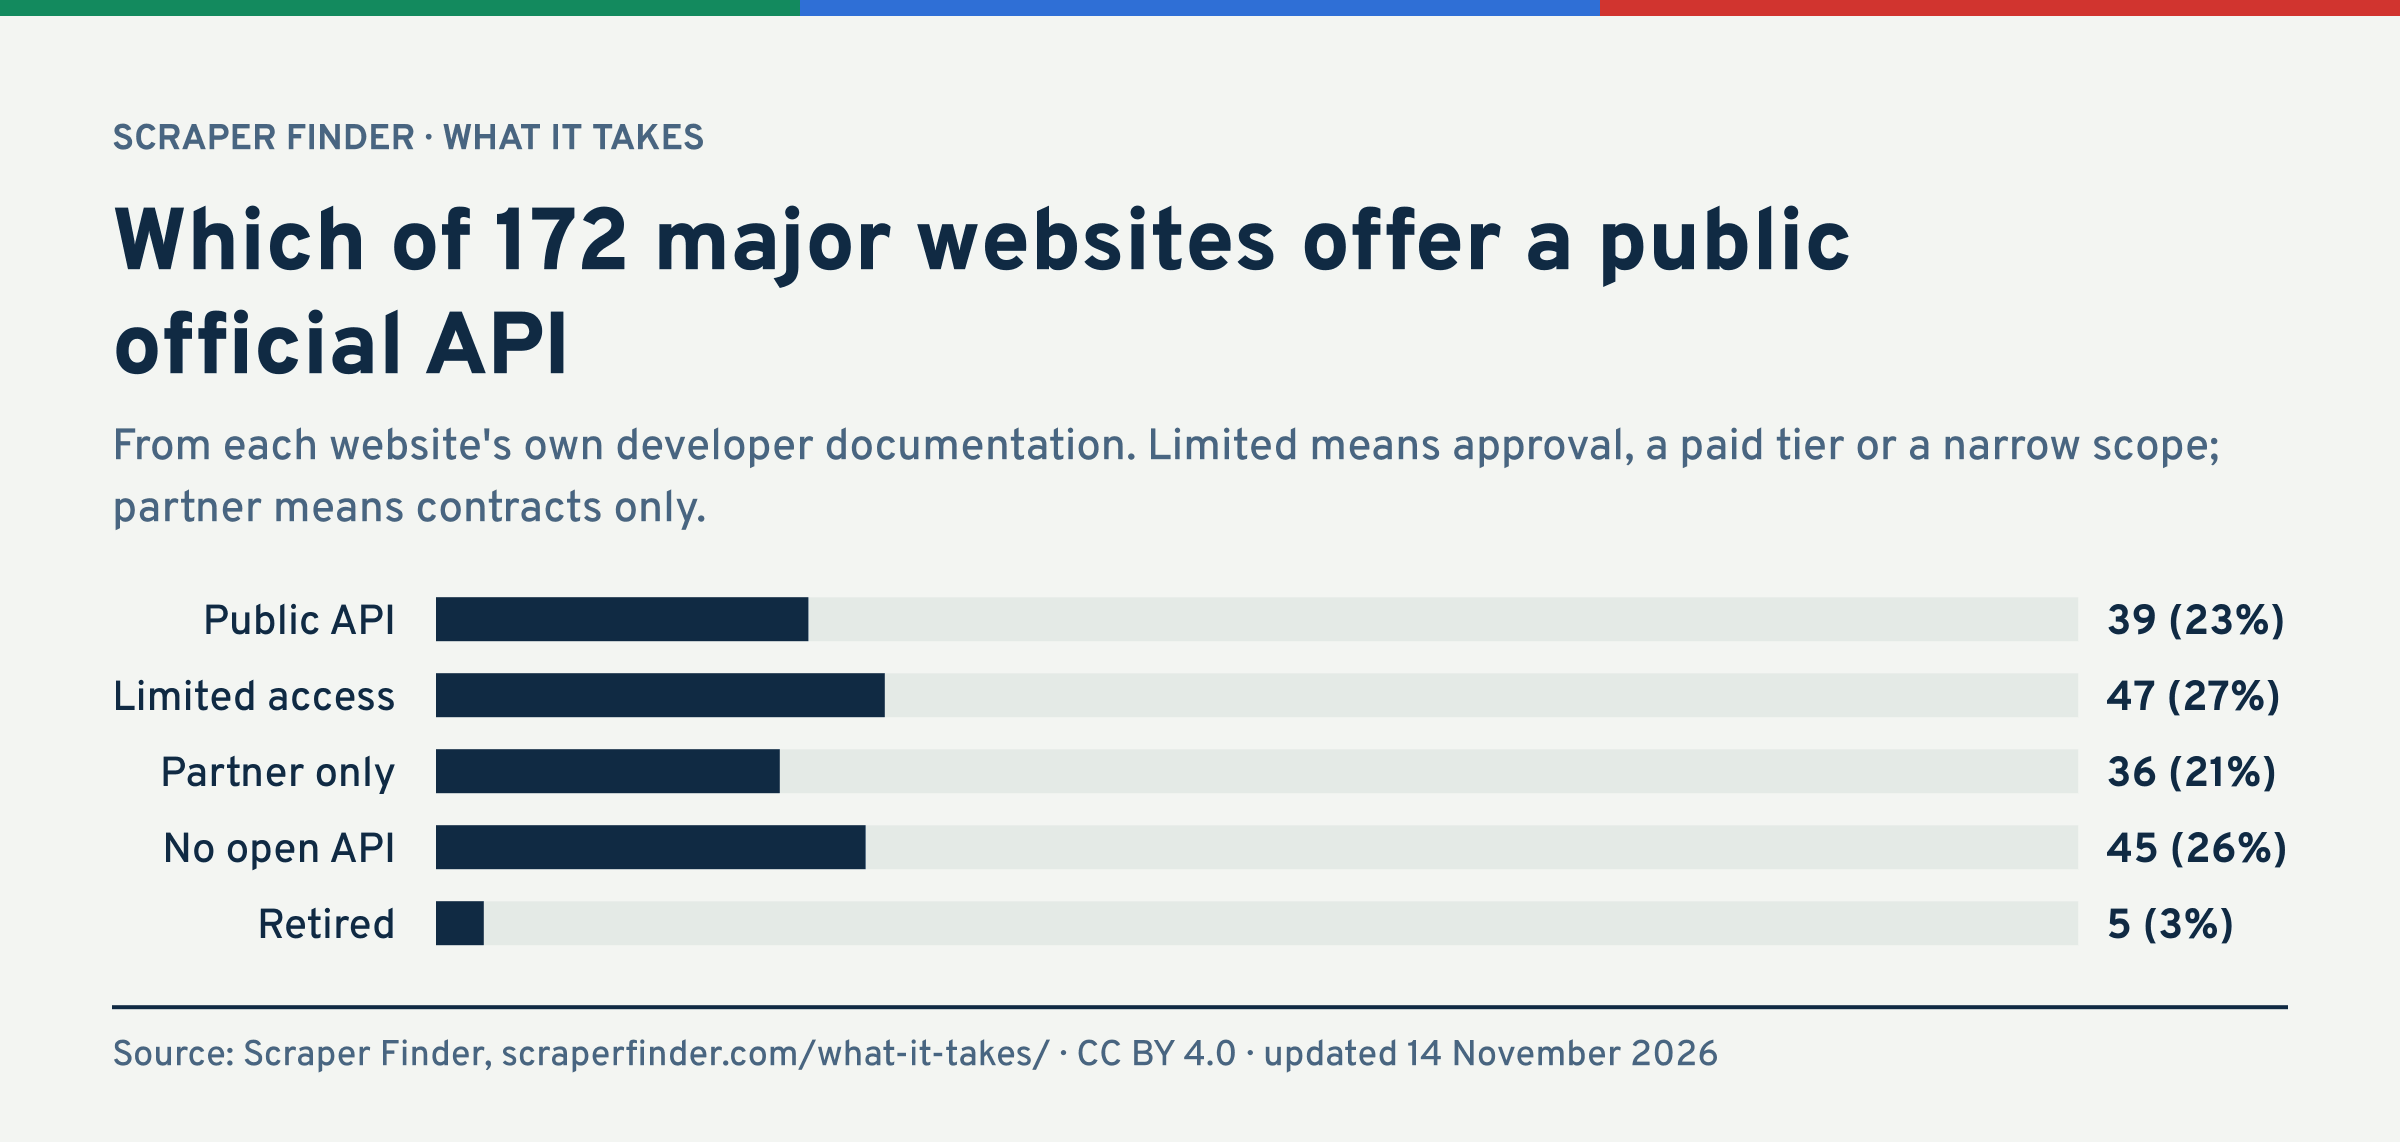
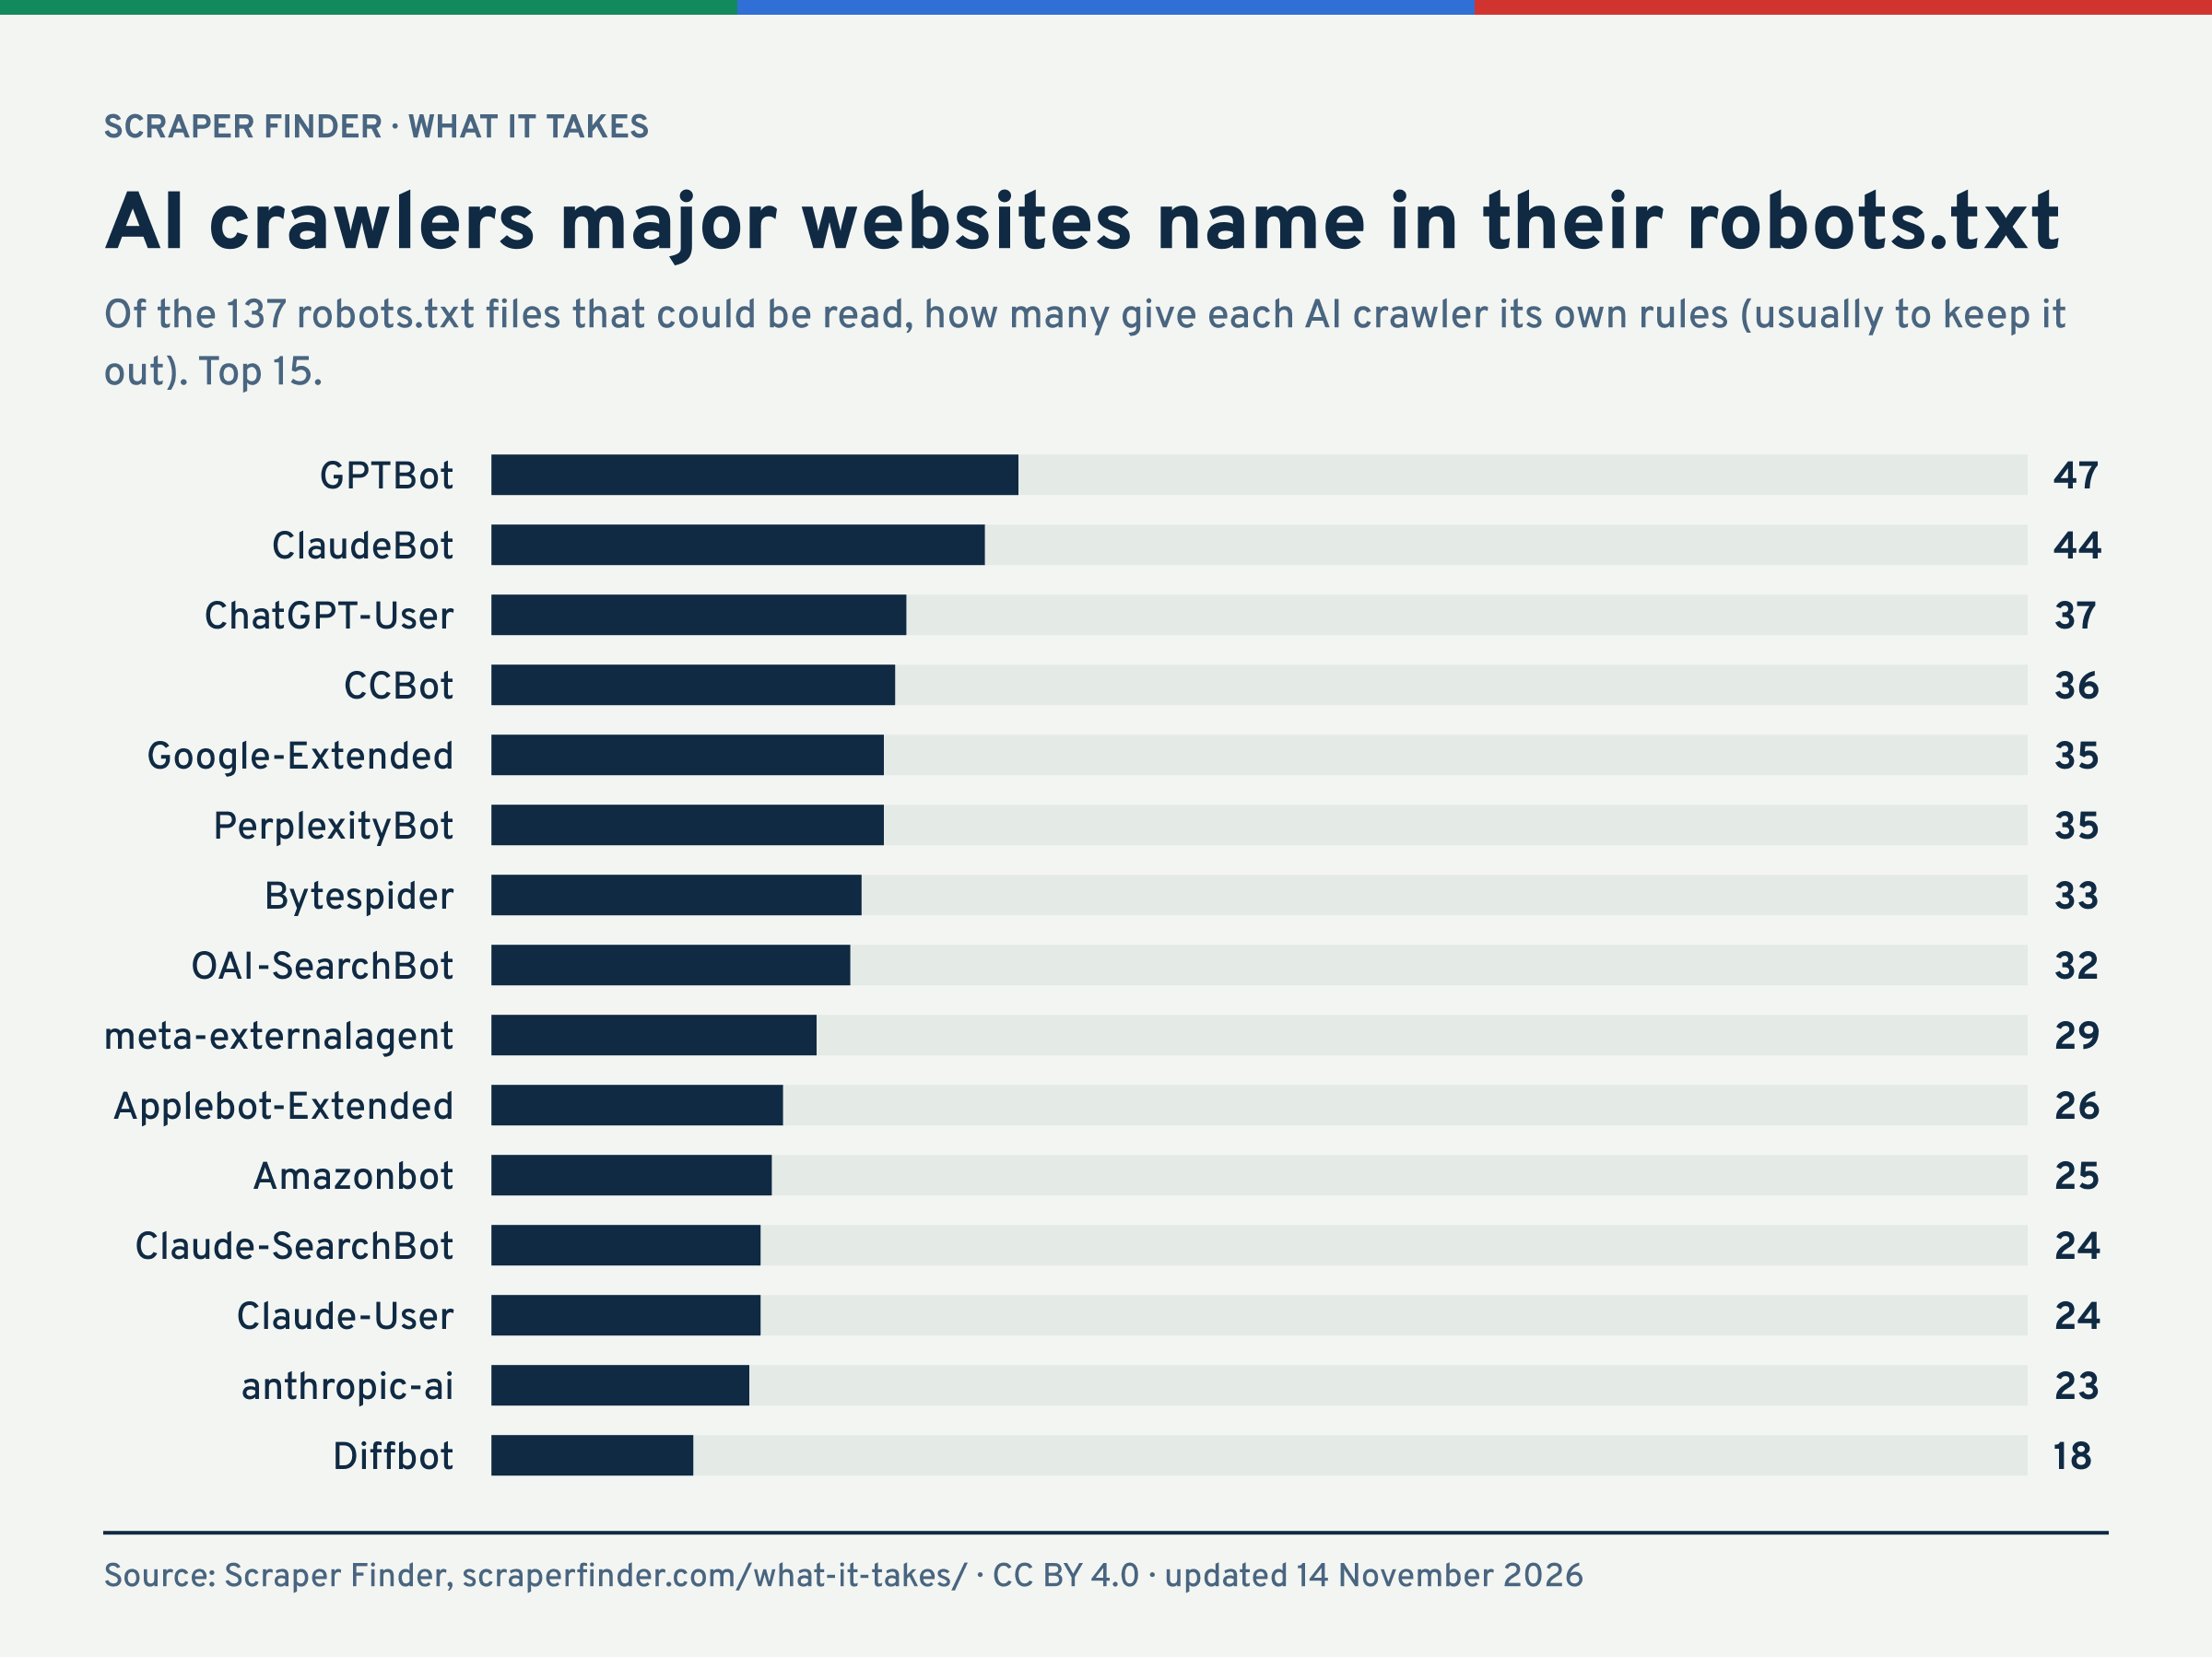
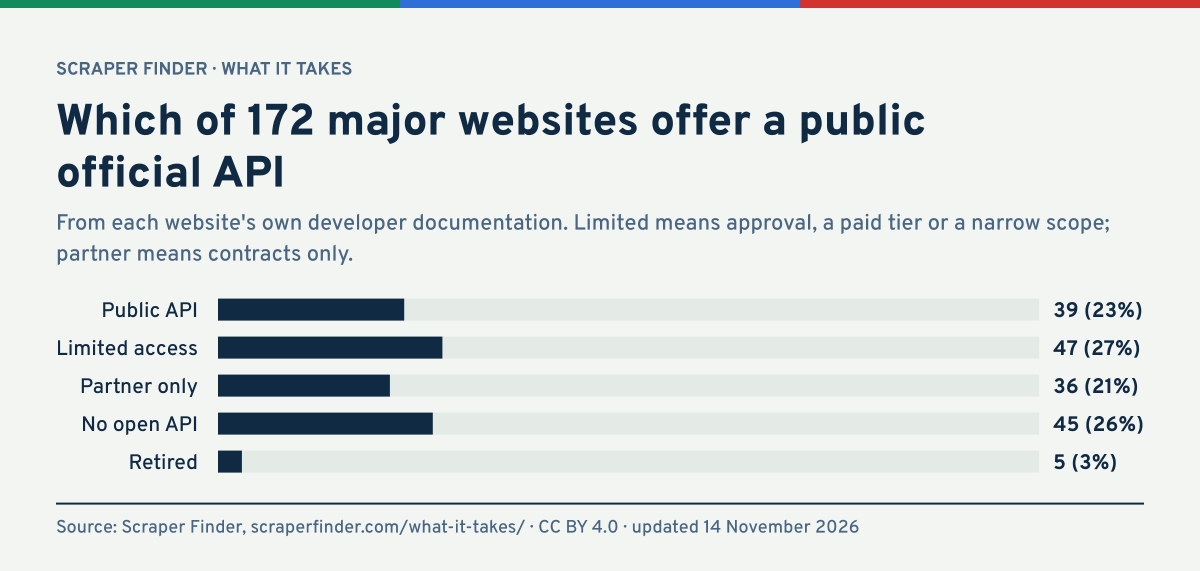
For 172 major websites: whether there is a public official API (39 have one), what robots.txt says to crawlers without their own rules (17 disallow every path), which AI crawlers it names, and whether one plain HTTPS request for robots.txt or the terms page is answered (58 refused). Court cases and open-source scrapers per website, each fact dated.
Type any domain: the checker reads its live robots.txt and shows, for each of the 34 AI crawlers and tokens in the directory, whether it is blocked, by which group and line, with a comparison against the 137 major websites in the weekly study. Shareable result links; nothing about the domains checked is stored.